Dispatch Patterns on Graphics Processors Influencing Team Sync in Indie Mobile Dev Leagues
Graphics processors manage thousands of threads through specialized scheduling units that allocate compute resources across shader cores, texture units, and memory controllers during runtime execution. In competitive mobile development leagues, these allocation decisions determine how quickly teams can iterate on rendering pipelines and physics simulations while maintaining consistent frame delivery across multiple devices. Observers note that scheduling patterns such as round-robin, priority-based, and wavefront execution directly affect latency when squads push synchronized updates to shared code repositories during live events.
Core Mechanisms Behind Thread Allocation
Modern mobile GPUs employ warp or wavefront schedulers that group threads into bundles executed in lockstep, and this grouping influences how efficiently parallel tasks like particle systems or lighting calculations complete under tight competition deadlines. Data from hardware performance counters shows that wavefront divergence occurs when conditional branches split execution paths, forcing the scheduler to serialize operations and extend overall frame times. Teams competing in July 2026 events have documented cases where adjusting thread block sizes reduced divergence penalties by measurable percentages, allowing faster turnaround on collaborative builds.
Memory access patterns further interact with scheduling because coalesced loads keep execution units busy while scattered accesses stall pipelines, and league participants track these stalls through profiling tools provided by device manufacturers. Studies from institutions such as the Technical University of Munich have measured how cache thrashing compounds with poor thread ordering, resulting in extended sync times when multiple developers commit changes simultaneously.
Effects on Squad Coordination During Live Events
Indie mobile development leagues require squads to maintain synchronized progress across art pipelines, gameplay logic, and network code, and GPU thread behavior shapes the feasibility of achieving sub-second iteration cycles. When schedulers favor compute-heavy workloads, rendering threads may queue behind simulation tasks, creating visible desyncs in test builds that force teams to adjust their division of labor. Research indicates that priority scheduling modes can mitigate this by elevating critical path threads, though such modes require explicit API calls that vary across OpenGL ES, Vulkan, and Metal implementations.
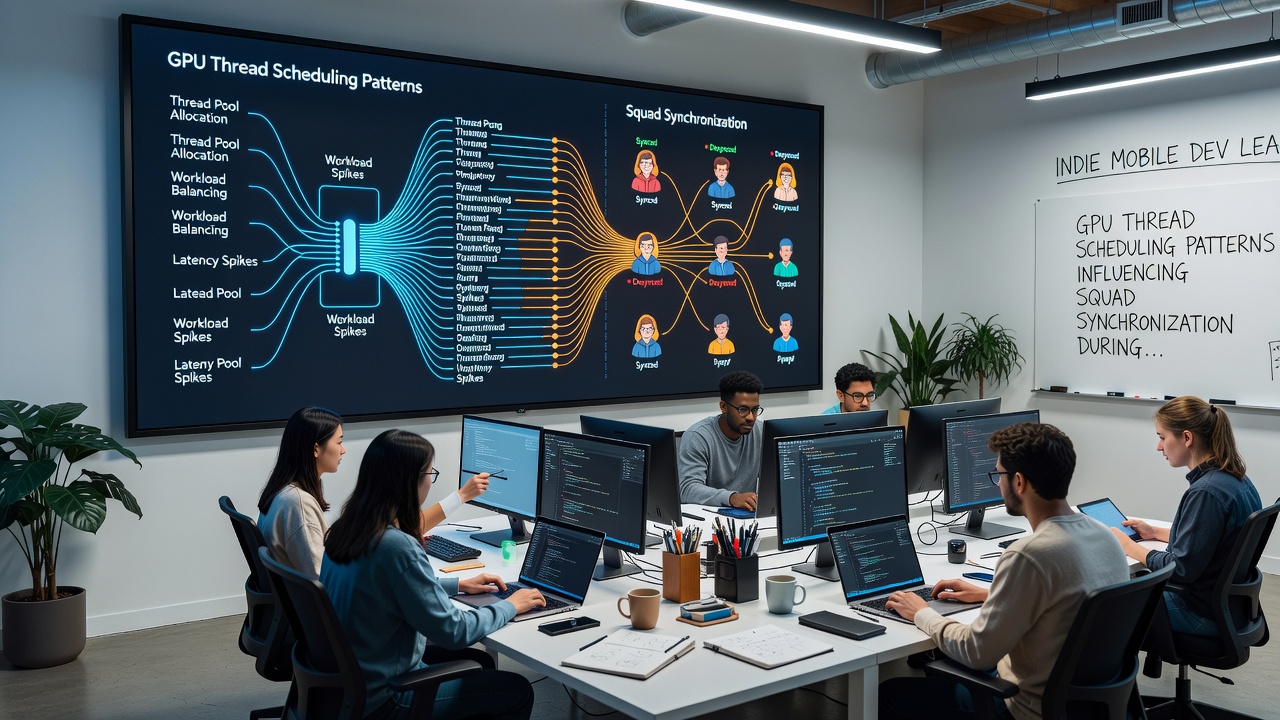
One documented instance from an Australian university study on embedded graphics systems revealed that dynamic thread reordering reduced average build validation time by 18 percent in multi-developer scenarios, and similar patterns appear in league telemetry collected during regional qualifiers. Squads that monitor occupancy metrics can redistribute workloads to underutilized cores, preserving frame consistency while other members integrate new assets or scripts.
Hardware Variations Across Mobile Platforms
Different chip architectures implement thread scheduling with distinct trade-offs, and participants in these leagues must account for variations between Adreno, Mali, and PowerVR designs when targeting cross-device compatibility. Figures from industry reports compiled by the Japan Electronics and Information Technology Industries Association highlight how Mali's forward pixel kill mechanism interacts with thread grouping to influence early rejection rates in fragment shaders. Teams that test on representative hardware during preparation phases identify scheduling bottlenecks before competition rounds begin, preventing last-minute adjustments that disrupt synchronized workflows.
Power management features add another layer because frequency scaling triggered by thermal limits alters the effective throughput of scheduled threads, and league organizers have begun requiring standardized device profiles to ensure fair comparison of development outputs. Data collected at events shows that consistent thermal envelopes allow more predictable thread execution timelines across squads.
Integration With Development Toolchains
Profiling suites integrated into mobile IDEs expose thread occupancy and stall reasons, enabling squads to correlate scheduling events with code changes in real time. According to documentation from the Khronos Group on Vulkan best practices, explicit control over command buffer submission order can influence how the driver maps work to available execution units. Participants who leverage these controls report improved alignment between individual contributions and collective milestones, particularly when handling compute shaders for procedural content generation.
Training sessions ahead of July 2026 tournaments have incorporated modules on these toolchain features, and attendance records indicate rising participation from smaller collectives seeking to optimize their synchronization strategies through hardware-aware coding practices.
Conclusion
Thread scheduling on graphics processors continues to shape coordination dynamics in indie mobile development leagues by setting the practical limits of parallel workload execution and iteration speed. Teams that understand wavefront behavior, memory coalescing, and platform-specific dispatch rules gain measurable advantages in maintaining synchronized progress under competitive conditions. As hardware evolves and league formats adapt, ongoing measurement of these patterns provides the factual basis for refined development approaches across events.